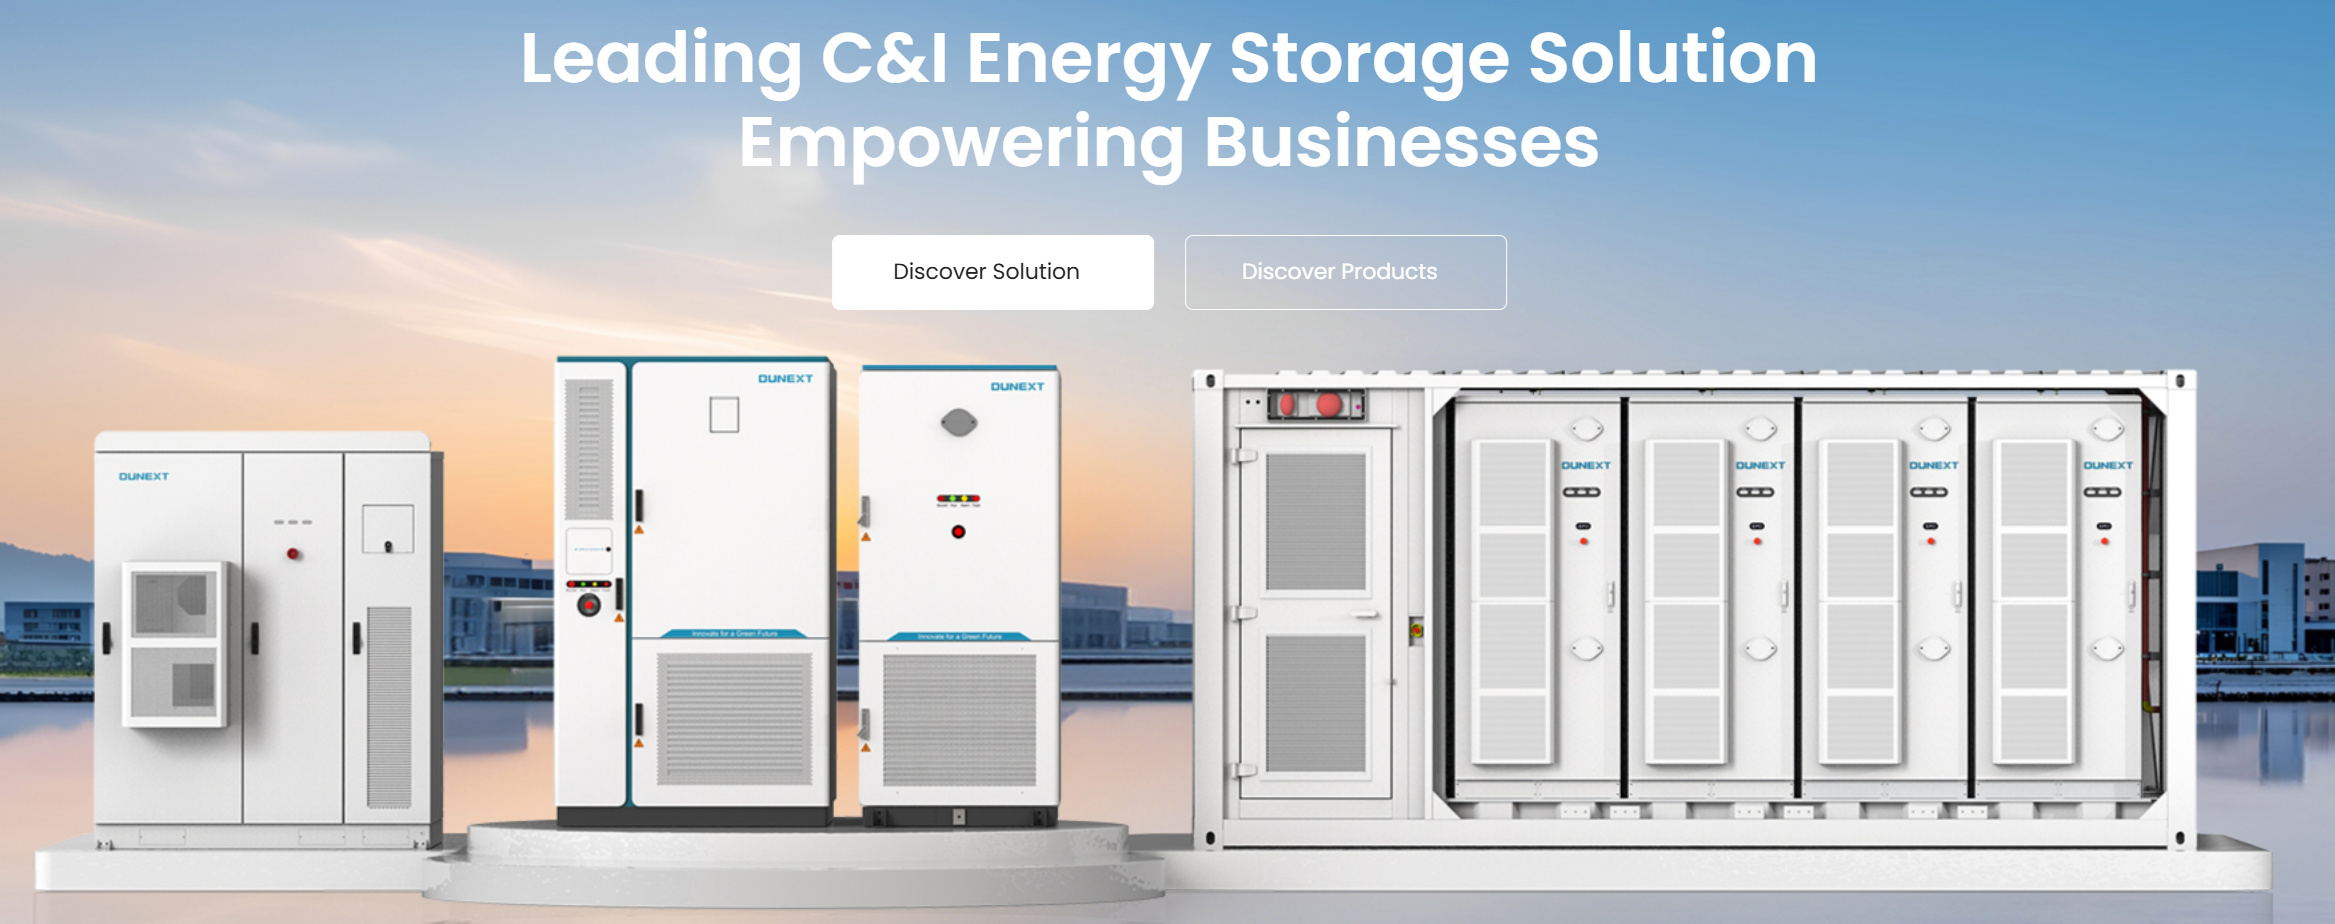
Face the core problem
Batteries don’t fail quietly; systems do. You need an architecture that stops surprises and keeps power predictable. Start by naming the worst-case failure you dread, then build around avoiding it. If you work with a local Dunext dealer, tell them that single failure and demand a clear mitigation path. Short mission: detect early, isolate fast, recover cleanly.
What the architecture must do — simple checklist
Focus on five tasks. If the design doesn’t do each of these, it won’t work under pressure.- Protect cells: cell-level monitoring, thermal management, and safe isolation.- Balance energy: state-of-charge (SoC) control and lifetime-aware charging.- Coordinate power: fast power conversion (PCS) and grid-interaction logic.- Make decisions: an energy management system (EMS) that prioritizes safety, revenue, and longevity.- Report clearly: logs, alarms, and performance dashboards that engineers trust.
Core components and how they fit
Keep component roles crisp. BMS protects cells and reports health. PCS converts DC/AC and enforces power limits. EMS schedules dispatch and trades revenue against wear. SCADA or cloud ties monitoring and control to operators. Communications must be deterministic: use isolated serial or industrial Ethernet and redundant paths for critical telemetry. Design the hierarchy: BMS -> PCS -> EMS -> Operator. Each layer must own a single responsibility and a clear fallback.
Sizing and control strategies that survive real use
Pick size by grid duty, not wishful thinking. For peak shaving, size to the peak window plus buffer for SoC margin. For arbitrage, favor cycles over peak power. Use these control rules:- Hard SoC limits for safety; soft SoC targets for revenue.- Rate-limit ramping to avoid thermal spikes.- Rolling-state estimation to catch SoC drift.Simulate typical days and the worst week. Don’t trust a single performance curve; test at temperature extremes.
Common failures and straightforward fixes
Problems repeat. Fix them with clear actions.- SoC drift: implement frequent recalibration events, monitor Coulomb counting vs. voltage curves.- Thermal hotspots: add zoned cooling and automatic derating thresholds.- Comms loss: design local autonomous behavior that keeps safety on even when EMS is offline.- Grid disturbance: ensure anti-islanding logic and ride-through capabilities.Document each failure mode and the exact cutover behavior. Train operators with drills that replicate those faults.
Comparing vendors without getting lost
Stop listening to specs alone. Use three practical tests when evaluating systems:- Fault response test: ask for a demonstration of a cell fault and watch isolation speed.- Data fidelity check: verify raw telemetry access and timestamp accuracy.- Lifetime math: demand test data showing calendar and cycle degradation assumptions.Evaluate product suites and include a hands-on pilot. When you review commercial energy storage batteries, weigh the control integration and maintenance plan more than peak efficiency numbers.
Proof from operations
Real deployments teach the harshest lessons. Look at California’s grid-scale battery deployments — they exposed thermal management and control coordination as the top operational stressors. Operators who adopted tighter SoC practices and clearer control hierarchies reduced urgent interventions. That kind of field feedback rewrites design priorities faster than theoretical models.
Close the loop — build a system you can rely on
Decide which failure matters most, then architect around preventing it. Keep roles simple, controls strict, and telemetry honest. Plan for human drills and real fault tests. The right architecture makes the system predictable and maintainable — the kind of practical reliability teams appreciate and suppliers deliver when they partner effectively with Dunext.